Benchmarking SI Models for AM
This project presents a comprehensive methodology for evaluating the capabilities of various existing SI tools in addressing diverse AM-related tasks. The focus is on establishing qualitative metrics that can help you assess and compare different SI models for additive manufacturing applications.
Key Concepts:
- Evaluation Framework: A structured approach to assess SI performance in AM contexts
- Qualitative Metrics: 35 metrics across three categories to comprehensively evaluate model capabilities
- Scoring Matrix: A practical tool for assessing different SI models on AM-specific tasks
- Comparative Analysis: Methods to benchmark various SI tools against each other
Our research evaluated several major SI models including GPT-4, GPT-3.5, Gemini (previously BARD), Llama 2, DALL·E 3, and Stable Diffusion across a range of AM-specific tasks using these metrics.
Qualitative Metrics Framework
Our benchmarking framework is built around 35 qualitative metrics organized into three main categories. This comprehensive set of metrics allows for a detailed assessment of how well different SI models perform on AM-related tasks.
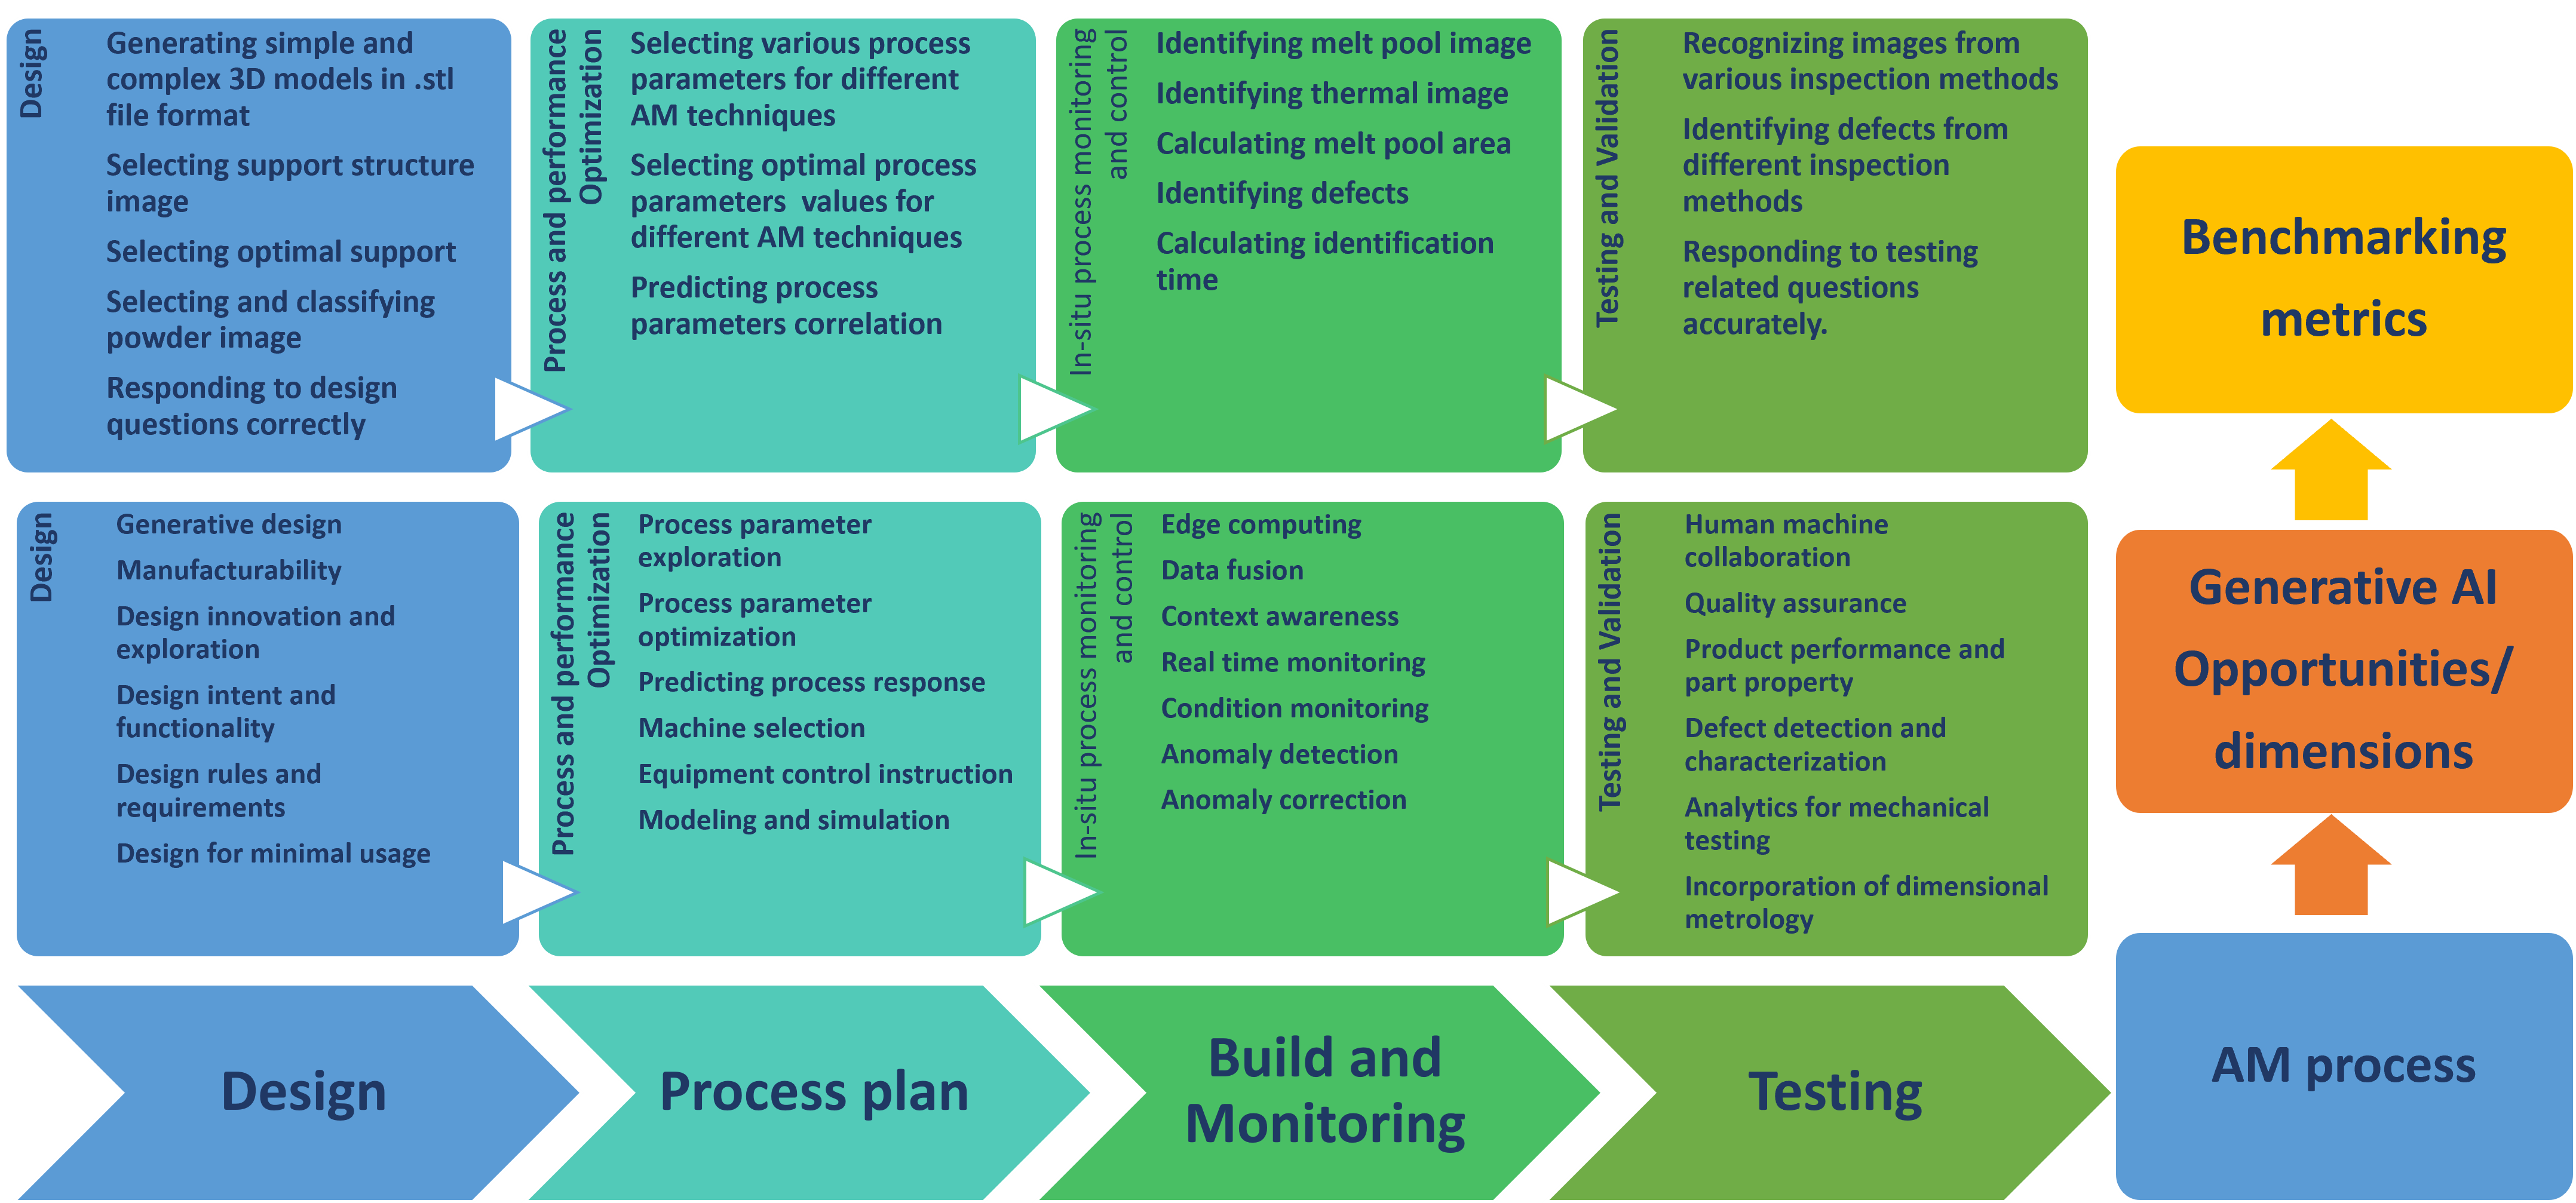
The three categories of qualitative metrics for evaluating SI models in AM
Metric Categories
The metrics are divided into three main categories, each addressing different aspects of SI performance:
Agnostic Metrics
General capabilities applicable across domains, including accuracy, coherence, and relevance.
Domain Task Metrics
Metrics specific to the additive manufacturing domain, such as AM knowledge and process understanding.
Problem Task Metrics
Metrics focused on specific AM problem types, like design generation, parameter optimization, and defect detection.
Source Code and Resources
For practical implementation of this benchmarking framework, you can access the following resources:
- GitHub Repository with implementation code and examples
- Standardized test queries for AM applications
- Sample scoring templates and evaluation protocols
Contribution
The wrok is a collaboration of Nowrin, Paul withrell, Vinay Saji, Soundar Kumara
Publication
If you are interested in the details, please refer to my following paper:
Current state and benchmarking of generative super intelligence for additive manufacturing, IDETC-CIE 2024.Learn More About SI Benchmarking
For more comprehensive understanding of benchmarking and evaluation, explore these related resources: